Reddit spent the month asking for the network you’re building. Heavy Metal isn’t in the threads yet.

Sam Altman called local inference “a terrible allocation of scarce resources”. r/LocalLLaMA answered with 2,893 comments and r/technology with 1,825, and Microsoft’s patent on idle gaming GPUs drew 1,686 more. People in those threads asked for “P2P inference like torrent” and a “SETI, but you get paid for your idle GPU”. Heavy Metal is named in none of the 30 live threads, or in the 51 that rank on Google. The beta opens in January. The weeks before it are for warming up accounts and putting the problem in front of these readers, so the name has somewhere to land.

12,818 comments
in 30 threads this month on agent limits, token bills, local models and idle hardware. All 30 are open.
The argument7,267
Limits and bills2,514
Owning hardware2,967
Pooling70
0 / 81
threads that name Heavy Metal: the 51 Google ranks for these searches and the 30 live this month
a thread without Heavy Metal
7.2M weekly
readers across the 14 subreddits where accounts would warm up
r/ClaudeAI2.2M
r/ClaudeCode1.3M
r/LocalLLaMA943K
r/homelab535K
9 posts
r/hermesagent asks of an account before its first promo post. 7 of the 14 subreddits gate promotion on history like this.
help, no mentionfirst post about you
01 · The argument

Altman said local inference wastes the world’s memory. Reddit answered with 7,267 comments in four threads.

r/LocalLLaMA · Oct 29Sam Altman: “Local inference is a terrible allocation of scarce resources”
6,735upvotes
2,893comments
0name Heavy Metal

Top reply: “The resources aren’t scarce, the rate to build them is.”

r/technology · Oct 30Altman: “terrible” for everybody to have the world’s limited DRAM in their own computer
12,138upvotes
1,825comments
0name Heavy Metal

Top reply: “They conceive of a world where they essentially control all devices bc they control all GPUs.”

r/pcmasterrace · Nov 14Microsoft patent to use idle gaming GPUs to train AI
12,738upvotes
1,686comments
0name Heavy Metal

Top reply, 15,489 upvotes: “I recall a time when that was called malware.”

r/technology · Oct 2479% of companies say their GPUs sit idle at least half the time
9,807upvotes
863comments
0name Heavy Metal

“Someone needs to invent Project SETI, but you get paid for your idle GPU at home.”

What readers proposed in those threads

“Can we have P2P inference like torrent but for open weight models?”

r/LocalLLaMA · under Altman’s quote

“Folks can find ways to pool their local compute, like the SETI@Home project.”

r/LocalLLaMA · under Altman’s quote

“Everyone could run a node, get credits, use credits, and buy more credits from people who are running faster nodes if required.”

r/technology · under Altman’s quote

“Someone needs to invent Project SETI, but you get paid for your idle GPU at home.”

The warning in the same threadsThe top reply to Microsoft’s patent, at 15,489 upvotes, is “I recall a time when that was called malware”. The next: “No one, will be using my GPU for their own goals” (4,152). Sharing compute lands when the owner chooses it and keeps control. That’s your own line, “Don’t rent your AI. Own it.”, and every seeded post keeps that frame.
Your answer to Altman
  • Posted on Eswar’s LinkedIn the next day
  • “Contribute that remaining 95% to a global inference pool and everybody wins!”
  • Not posted on Reddit
Where the argument happened
  • r/LocalLLaMA, 2,893 comments, still open
  • 943K weekly readers, the people who run open models
  • No answer from Heavy Metal yet
02 · The problem, in their words

Renting means limits that move. Owning means thousands in hardware. The middle is what you’re building.

Renting

Limits that move

Owning

Hardware that costs years of subscriptions

Pooling

The middle, and what you’re building

All 30 live threads · 12,818 comments · Heavy Metal named in none

The argument · 4Limits and bills · 11Owning hardware · 14Pooling · 1
r/LocalLLaMASam Altman: “Local inference is a terrible allocation of scarce resources”2,893 comments · Oct 29 r/technologyOpenAI CEO Sam Altman says its “terrible to have everybody have a bunch of the world’s limited supply of DRAM” instead of shoving it all in datacentres1,825 comments · Oct 30 r/pcmasterraceMicrosoft patent to use idle gaming GPUs train AI1,686 comments · Nov 14 r/pcmasterraceIf you hate AI memory crisis, just stop using cloud AI models and switch to local LLMs. This is Sam Altman's worst nightmare.1,270 comments · Nov 15 r/technologyAI bubble update: 79% of companies say their GPUs sit idle at least half the time, yet most plan new AI platforms863 comments · Oct 24 r/ClaudeCodePeople who hit their Claude limits every week: what on earth are you building?779 comments · Nov 5 r/ClaudeAILimits got at least halved?389 comments · Oct 26 r/homelabSelf hosted AI- how bad is it?302 comments · Nov 16 r/codexUnified limits are coming in december301 comments · Oct 29 r/technologyOpenClaw creator says he spent $10 million in tokens last month243 comments · Oct 21 r/LocalLLMDoes the M5 Max Mac Studio with 128GB RAM actually get you closer to frontier-level AI? or just a gimmick195 comments · Nov 10 r/ClaudeCodeDid You Ever Pay $100–$200 for a Subscription Before AI?179 comments · Oct 25 r/ClaudeCodeyou are not running out faster , the weekly usage limit is shirking ~[ 20% drop ]168 comments · Nov 13 r/LocalLLMIs local AI becoming a luxury hobby instead of a practical alternative?151 comments · Oct 27 r/ClaudeCodeClaude Code’s $100/month plan: 73% of my weekly limit gone in 2 days150 comments · Oct 28 r/LocalLLMIs running a local AI actually worth it? I'd love to hear about your experience!150 comments · Nov 3 r/LocalLLaMAWhere does local AI need to improve on before it has a broader appeal?137 comments · Nov 20 r/MacStudioLocal LLMs << Subscription135 comments · Nov 14 r/LocalLLMA comparable local setup for someone using $100 monthly claude subscription131 comments · Nov 17 r/LocalLLMThe day has come guys. My company banned the use of AI-assisted coding for privacy reasons. I'm hesitant to invest.128 comments · Oct 26 r/MacStudioDo I Actually Need a Mac Studio for Local AI, or Am I About to Waste Thousands of Dollars?103 comments · Nov 9 r/LocalLLaMAClaude Code enjoyer wanting to go local. What would your newbie harness of choice be?92 comments · Nov 3 r/hermesagentHow expensive is Hermes + DeepSeek in practice?83 comments · Nov 18 r/ClaudeCodeSo are you planning to pay for LLMs forever (or foreseeable future) every month or what's the plan?76 comments · Nov 20 r/hermesagentCheapest subscription75 comments · Nov 6 r/ArtificialInteligenceThe cost issue with AI that no one talks about (when will the subsidies end?)71 comments · Oct 24 r/LocalLLMI made a distributed chatbot that runs a 27B model across consumer GPUs, entirely in the browser (open source)70 comments · Oct 29 r/macminiWho else is using a Mac mini as a home AI box? What do you actually run on it?62 comments · Nov 6 r/hermesagentAnyone running Hermes fully local? What model and engine actually keeps up?61 comments · Nov 19 r/LocalLLMBuying into Local AI for tech sovereignty50 comments · Oct 27
03 · Named instead

Ollama is named in 38 of the 81 threads. Heavy Metal in none.

How people run models, by threads that name each, of the 81: the 51 that rank and the 30 live ones

Ollama38/81
llama.cpp25/81
OpenRouter25/81
LM Studio22/81
OpenCode Go13/81
vLLM11/81
MLX9/81
exo7/81
RunPod5/81
Vast.ai4/81
Heavy Metal0/81

The models they run are open-weight. Threads naming each:

Qwen 48DeepSeek 43GLM 30Kimi 21MiniMax 16

People already know the models. The open question in these threads is where to run them: a $20 plan that hits its limit, a Mac Studio that costs years of plans, or a rented GPU by the hour. That’s where Heavy Metal fits, and it’s the answer nobody gives yet.

04 · How the idea lands

Asking for pooled inference drew 1,019 upvotes on r/LocalLLaMA. Shipped projects drew 24 to 469.

asking for itsomething shippedbar length · upvotes
We should set up a torrent network for open source modelsr/LocalLLaMA · Jun 2026 · 163 comments
1,019
203
Exo 1.0 is finally outr/LocalLLaMA · Dec 2025 · 58 comments
152
Petals: decentralized inference and finetuning of LLMsr/LocalLLaMA · Jul 2023 · 31 comments
116
Why don’t we have a proper BitTorrent for LLMs?r/LocalLLM · Aug 2026 · 34 comments
31
Introducing LlamaNet: Decentralized AI Inference Networkr/LocalLLaMA · Sep 2025 · 23 comments
24

The demand is already on record, and so are the projects that tried. The ones that drew hundreds named the model, the machines and the speed: EXO’s DeepSeek R1 across two Mac Studios at 11 tokens a second, a 27B model on a 3090 plus an old 1070 Ti. That’s the bar for the beta post.

05 · Your name

On Reddit, “Heavy Metal Network” is a death-metal band’s YouTube show. The first threads about you will decide what it means.

Every Reddit post with the name · none about you

Google, page one

heavy metal network2heavymetal.network #2 · LinkedIn #1, then the UK government’s heavy-metals air monitoring network, metal radio · no Reddit thread about you
heavy metal network ai1heavymetal.network #1 · Eswar’s LinkedIn #2, then heavy-metal pollution and detection papers · no Reddit thread about you
heavy metal inference1heavymetal.network #1 · heavy-metal exposure and pollution studies · no Reddit thread about you

Google already ties the name to you when it sits next to “inference” or “ai”. Reddit has nothing yet, so every post says Heavy Metal Network and inference network together, the way your site does.

06 · Search

Reddit is on page one for 51 searches in your space. #1 on 26 of them, top three on 47.

1Reddit thread, Google position upvotes comments archived or locked
SearchGoogle position 1–10Top ranking Reddit threadIn the thread
Limits and billsagents that stop, or cost too much · 13 searches
claude code rate limit2r/ClaudeAIClaude API Error: Rate limit reached?1064Feb 2026openHeavy Metal absentno inference option named
claude code weekly limit1r/ClaudeCodeI went from exhausting Claude Code’s weekly limits in 2 days to making them last the entire week. Here’s my setup26285Oct 2026openHeavy Metal absentNamed: DeepSeek 1
claude max worth it1r/ClaudeCodeIs claude max worth it?326May 2026openHeavy Metal absentNamed: OpenCode Go 1, OpenRouter 1
claude code too expensive1r/AI_AgentsClaude is WAY TOO EXPENSIVE5876Jul 2026openHeavy Metal absentNamed: DeepSeek 2, GLM 2, Kimi 1
claude code api cost3r/ClaudeAIWhat API cost do you think equals the $20/month Claude Pro plan?526Nov 2026openHeavy Metal absentno inference option named
cheapest way to use claude code1r/ClaudeAICheapest way for a student to use Claude for coding?5477Mar 2026openHeavy Metal absentNamed: DeepSeek 1, Ollama 1, OpenRouter 1
openclaw api cost3r/openclawHow much are you spending on API for OpenClaw?521Feb 2026openHeavy Metal absentNamed: Kimi 4, OpenRouter 4, Qwen 2
openclaw expensive1r/openclawAm I doing it wrong, or is using OpenClaw just super expensive?37147Apr 2026openHeavy Metal absentNamed: Ollama 8, MiniMax 7, GLM 3
hermes agent cost2r/hermesagentHow much do you guys spend on AI costs monthly2056May 2026openHeavy Metal absentNamed: DeepSeek 8, OpenRouter 3, Qwen 3
ai coding agent cost per month5r/vibecodingBest price-to-performance AI coding agents right now (beyond GitHub Copilot)?114Jun 2026openHeavy Metal absentNamed: Command Code 1, DeepSeek 1, GLM 1
cheapest llm api for coding1r/ArtificialInteligenceCheaper LLM API providers compared to OpenAI, Anthropic and perplexity2059Mar 2026openHeavy Metal absentNamed: Groq 4, Cerebras 2, DeepSeek 2
openrouter alternative1r/openrouterAny alternatives to openrouter?2641Apr 2026lockedHeavy Metal absentNamed: Ollama 6, DeepSeek 5, OpenRouter 5
openrouter free models7r/CLineDecent Free Models from OpenRouter (did some testing today)3618May 2025openHeavy Metal absentNamed: OpenRouter 6, DeepSeek 4, Chutes 2
Open models in your agentClaude Code, OpenCode, OpenClaw and Hermes on open models · 14 searches
claude code with local model1r/LocalLLaMAUse claudecode with local models16556Jul 2025openHeavy Metal absentNamed: Kimi 6, llama.cpp 3, DeepSeek 2
claude code open source model1r/LocalLLMAre there any open-source Claude Code style tools that I can use to define a workspace and have a locally hosted model perform a myriad of tasks and interface with a ton of files?212May 2026openHeavy Metal absentNamed: Ollama 1, OpenCode Go 1, Qwen 1
claude code with glm2r/ClaudeCodeGLM-5 just dropped - here's how to run it in Claude Code in one command11933Feb 2026openHeavy Metal absentNamed: GLM 7
claude code with kimi k22r/vibecodingHow I'm using Kimi K2 in Claude Code2616Jul 2025openHeavy Metal absentNamed: Kimi 3, OpenRouter 3, DeepSeek 1
claude code with qwen1r/ollamaClaude Code + Qwen 3.5 locally on IDE?513Mar 2026openHeavy Metal absentNamed: Ollama 7, Qwen 6
claude code ollama2r/LocalLLMClaude Code running locally with Ollama15951Mar 2026openHeavy Metal absentNamed: Ollama 5, Qwen 5, llama.cpp 2
opencode local model3r/opencodeCLIWhat local LLM models are you using with OpenCode for coding agents?1362Mar 2026openHeavy Metal absentNamed: Qwen 15, llama.cpp 5, GLM 3
opencode best model2r/opencodeCLIWhich model should i choose for coding2940Feb 2026openHeavy Metal absentNamed: MiniMax 3, GLM 2, OpenCode Go 2
openclaw local model2r/LocalLLMWhat are your preferred local model for running OpenClaw?316Feb 2026openHeavy Metal absentNamed: Qwen 4, GLM 3, MiniMax 2
openclaw ollama3r/ollamaHow to hook up OpenClaw to Ollama? Claude is too expensive lol620Feb 2026openHeavy Metal absentNamed: Ollama 9, GLM 1, Kimi 1
hermes agent local model3r/hermesagentWhich local model gives the best experience with Hermes Agent + LM Studio?1844Jul 2026openHeavy Metal absentNamed: Qwen 13, DeepSeek 5, LM Studio 2
best open source model for coding2r/LocalLLMWhich open source/open weight local LLM should I try for coding purposes.1525Jul 2026openHeavy Metal absentNamed: GLM 7, Qwen 7, DeepSeek 3
best local model for coding agent1r/LocalLLMbest local coding-agent model for my setup (web dev use case)011Apr 2026openHeavy Metal absentNamed: Qwen 4, LM Studio 2, DeepSeek 1
qwen3 coder local1r/LocalLLaMABest Way to Use Qwen3-Coder for Local AI Coding?5850Aug 2025openHeavy Metal absentNamed: Qwen 13, LM Studio 5, llama.cpp 4
The machines people ownMacs, GPUs and home clusters · 14 searches
run llm on mac2r/MacOSBest tool to run llm on mac m chips and can deliver real productivity gains?1321Apr 2026openHeavy Metal absentNamed: Ollama 7, LM Studio 5, Qwen 4
mac studio for llm1r/LocalLLaMAI am considering buying a Mac Studio for running local LLMs. Going for maximum RAM but does the GPU core count make a difference that justifies the extra $1k?401349Feb 2025openHeavy Metal absentNamed: DeepSeek 7, llama.cpp 3, LM Studio 2
best mac for local llm1r/LocalLLMWhich MacBook should I choose to run local LLMs (including open-source GPT-like models)?845Apr 2026openHeavy Metal absentNamed: Qwen 2
macbook pro local llm1r/LocalLLaMAAny experiences running LLMs on a MacBook?2058Jul 2025openHeavy Metal absentNamed: Qwen 10, MLX 6, LM Studio 5
local llm too slow1r/LocalLLaMAhow many people will tolerate slow speed for running LLM locally?171167Jun 2025openHeavy Metal absentNamed: Qwen 6, DeepSeek 2
is it worth running llm locally2r/LocalLLaMAIs local LLM really worth it or not?74131May 2025openHeavy Metal absentNamed: Qwen 7, DeepSeek 4, OpenRouter 3
local llm vs api cost1r/LocalLLaMABut why Local LLM? How does this make economic sense vs API?038Apr 2026openHeavy Metal absentNamed: MiniMax 2, OpenRouter 2
run llm on multiple macs1r/ollamaCan I combine 2x M4 Pro MacBooks for LLMs? And what Ollama models can I run?326Jun 2025openHeavy Metal absentNamed: exo 4, Ollama 3, vLLM 2
exo cluster mac3r/LocalLLaMAExo labs claiming 4.8 tb/s memory bandwidth through m5u Mac Studio clustering174142Aug 2026openHeavy Metal absentNamed: exo 10, MLX 3, GLM 1
mac mini cluster llm1r/LocalLLMHas anyone figured out clustering Mac Minis?13Nov 2025openHeavy Metal absentNamed: MLX 1
combine gpus from multiple computers llm2r/LocalLLaMADistributed Local LLM Swarm using multiple computers instead of one powerful GPU116Apr 2026openHeavy Metal absentNamed: Ollama 1, exo 1, llama.cpp 1
distributed llm inference across devices6r/LocalLLMHas anyone tried running a distributed LLM across multiple phones?116Aug 2026openHeavy Metal absentNamed: Qwen 3, Petals 2, llama.cpp 2
rent out my gpu2r/gpuminingBest platform to rent out my GPUs?62100Aug 2023openHeavy Metal absentNamed: Vast.ai 2
earn money with idle gpu1r/homelabWhat Are Your Thoughts on Earning Passive Income from Idle Compute Power?011Feb 2025openHeavy Metal absentno inference option named
Renting vs owning computeGPU clouds, self-hosting, decentralized inference · 10 searches
cheapest gpu cloud for inference1r/LocalLLaMACost-Effective Cloud GPU Options for Fine-Tuning and Inference?1345Nov 2024openHeavy Metal absentNamed: RunPod 7, Vast.ai 4, Nebius 1
rent gpu for llm2r/LocalLLaMAWhere do you all rent GPU servers for small ML / AI side projects?1681Feb 2026openHeavy Metal absentNamed: Vast.ai 4, RunPod 3, Qwen 2
self hosted llm for coding1r/selfhostedAnyone self host an llm for coding?032Mar 2026openHeavy Metal absentNamed: Ollama 5, Qwen 4, MiniMax 2
private llm for coding1r/LocalLLMBest local LLM setup for coding? Complete hardware beginner here.2443Nov 2026openHeavy Metal absentNamed: Qwen 8, OpenRouter 2, Ollama 1
data sovereignty llm3r/softwarearchitectureWhy calling public LLM APIs breaks enterprise sovereignty (and how to architect a true Sovereign AI stack in VPC/On-Prem)03Oct 2026openHeavy Metal absentNamed: vLLM 1
decentralized ai inference1r/LLMWhy is nobody talking about decentralized inference? (BitTorrent-style for LLMs)4446Feb 2026openHeavy Metal absentNamed: Petals 3, Chutes 2, DeepSeek 1
decentralized gpu network3r/dataengineeringDecentralized compute for AI is starting to feel less like a dream and more like a necessity3714May 2025archivedHeavy Metal absentNamed: Hyperbolic 1
run your own ai4r/selfhostedThe Complete Guide to Building Your Free Local AI Assistant with Ollama and Open WebUI32980Mar 2025openHeavy Metal absentNamed: Ollama 7, DeepSeek 1, MiniMax 1
local ai for privacy1r/aiToolForBusinessI’ve been looking into local AI tools for business privacy. here’s what seems worth watching16Jun 2026openHeavy Metal absentNamed: LM Studio 1, Ollama 1
ai compute costs1r/ArtificialInteligenceNvidia's VP says compute now costs more than employees. Uber just proved it by burning its entire AI budget in 4 months.27969Jun 2026openHeavy Metal absentNamed: DeepSeek 2
49 of 51 are openAnyone can still reply to them, and an answer stays under the result for as long as it ranks. The closest to what you do is “Why is nobody talking about decentralized inference?”, Reddit’s #1 result for decentralized ai inference. Search isn’t the priority before a beta, so these come after launch, on the Ranking plan.
07 · Where accounts warm up

14 subreddits, 7.2M weekly readers. Half of them want an account’s history before it promotes anything.

gates promotion on an account’s history
r/ClaudeAI2.2MPromotion is fine for things built with or for Claude, explained in detail
r/ClaudeCode1.3MProjects go in the weekly showcase thread
r/LocalLLaMA943KhistorySelf-promotion kept to about 1 in 10 posts
r/homelab535KhistoryNo company ads; software projects need minimum subreddit karma
r/selfhosted515KPromoted apps must be production-ready, with docs
r/LocalLLM466KhistorySelf-promotion under 10% of what an account posts
r/codex415KhistoryComment karma in r/codex decides how high posts show
r/AI_Agents290KhistoryLinks go in comments; about 1 in 10 self-promotion
r/MacStudio138KPromotion has to relate to the Mac Studio
r/hermesagent134Khistory9 community contributions before a showcase or promo post
r/macmini101KNo self-promotion posts
r/ollama79Khistory9 non-promotional contributions for every promotional one
r/opencodeCLI71KPosts must be about opencode
r/LLMDevs62KDisguised marketing is a permanent ban

This is why the work starts now, not in January. An account that joins r/hermesagent in beta week can’t post about Heavy Metal until it has 9 contributions there. r/codex ranks posts by the comment karma an account earned in r/codex. Accounts that start answering questions in November arrive at the beta with that history already in place.

08 · The plan

Warm up now, seed the problem in December, launch in January. Then answer the threads that rank.

Now → mid-December · Warm upAccounts answer questions in r/LocalLLaMA, r/LocalLLM, r/hermesagent, r/codex, r/ollama and r/homelab. No product mentions yet.
Mid-December → beta · SeedReplies in the open argument threads, discussions on renting vs owning, and the founder account saying what Heavy Metal is building
Beta week, January · LaunchOne post per subreddit over 48 hours, from a disclosed founder or team account, showing it running
Day 90Re-measure the baseline

Warm up: answer what’s being askedExposure

  1. r/LocalLLaMA: Claude Code enjoyer wanting to go localwhich harness and model to start with
  2. r/hermesagent: Anyone running Hermes fully local?model and engine that keep up
  3. r/LocalLLM: A comparable local setup for a $100 Claude subscriptionwhat local hardware really replaces
  4. r/macmini: Using a Mac mini as a home AI boxwhat an always-on Mac can run
  5. r/homelab: Self hosted AI, how bad is it?302 comments, sizing and cost
  6. r/hermesagent: How expensive is Hermes + DeepSeek in practice?monthly bills, by setup

Seed: the problem, then the nameExposure

  1. r/LocalLLaMA: Altman’s “terrible allocation” thread2,893 comments, still open: the owner-controlled pool, from the founder account
  2. r/LLM: Why is nobody talking about decentralized inference?Reddit #1 for “decentralized ai inference”, still open
  3. r/LocalLLM: Why don’t we have a proper BitTorrent for LLMs?the same question, asked in August
  4. r/technology: 79% of company GPUs sit idlewhere “SETI, but you get paid” was asked
  5. New discussion: your Mac sits idle most of the day. What would you let it run, and on whose terms?r/MacStudio · r/macmini · r/LocalLLM
  6. New discussion: Codex merges its limits in December. What’s your plan for agents that run all day?r/codex · r/ClaudeCode · r/hermesagent

Beta week: show it runningExposure

  1. r/LocalLLaMA: the beta post, with a named model, the machines it ran across and tokens per secondfounder account, inside the 1 in 10
  2. r/hermesagent and r/opencodeCLI: Hermes and OpenCode on Heavy Metal, the setup step by stepShowcase flair, after 9 contributions
  3. r/ClaudeCode and r/ClaudeAI: Claude Code on open models through Heavy Metalweekly showcase thread · built-for-Claude details
  4. r/MacStudio and r/macmini: put an idle Mac in the pool, opt-in, owner sets the hoursMac-specific, as their rules ask
  5. After the beta: answers in the 49 open threads that rank on Googlethe Ranking plan

House rules

Help firstWarm-up answers never mention Heavy Metal. They build the history r/hermesagent, r/ollama, r/codex and r/homelab ask for.
Say who you areProduct and launch posts come from a disclosed founder or team account. Other accounts answer questions. None of them poses as a beta user.
Owner’s choiceEvery mention frames sharing compute as opt-in, on the owner’s terms. Microsoft’s patent showed how the other framing lands.
Show it runningNo waitlist-only posts. Each product post names the model, the machines and the speed, like the posts that drew hundreds of upvotes.

The baseline we re-measure at day 90

MeasureTodayDay 90
Threads naming Heavy Metal0/81re-measure
Open argument threads with an answer from Heavy Metal0/4re-measure
Reddit posts about Heavy Metal Network, the inference network0 vs 5 about the band’s showre-measure
Waitlist and beta signups from Reddit, by UTM link–from day 1
09 · Proof

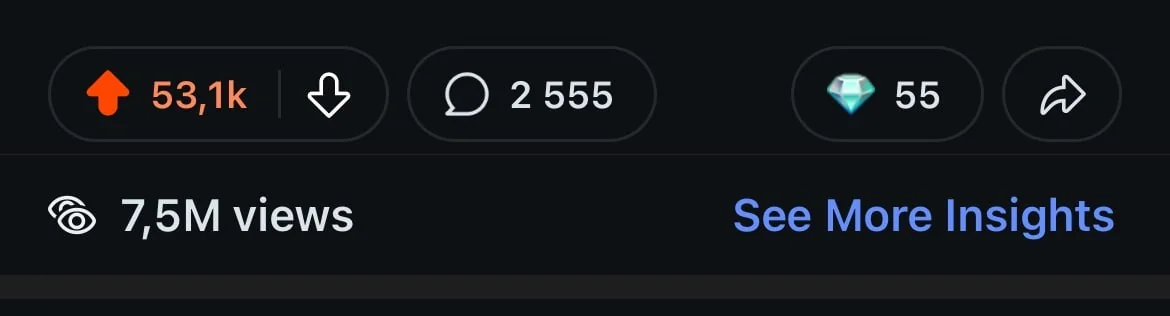
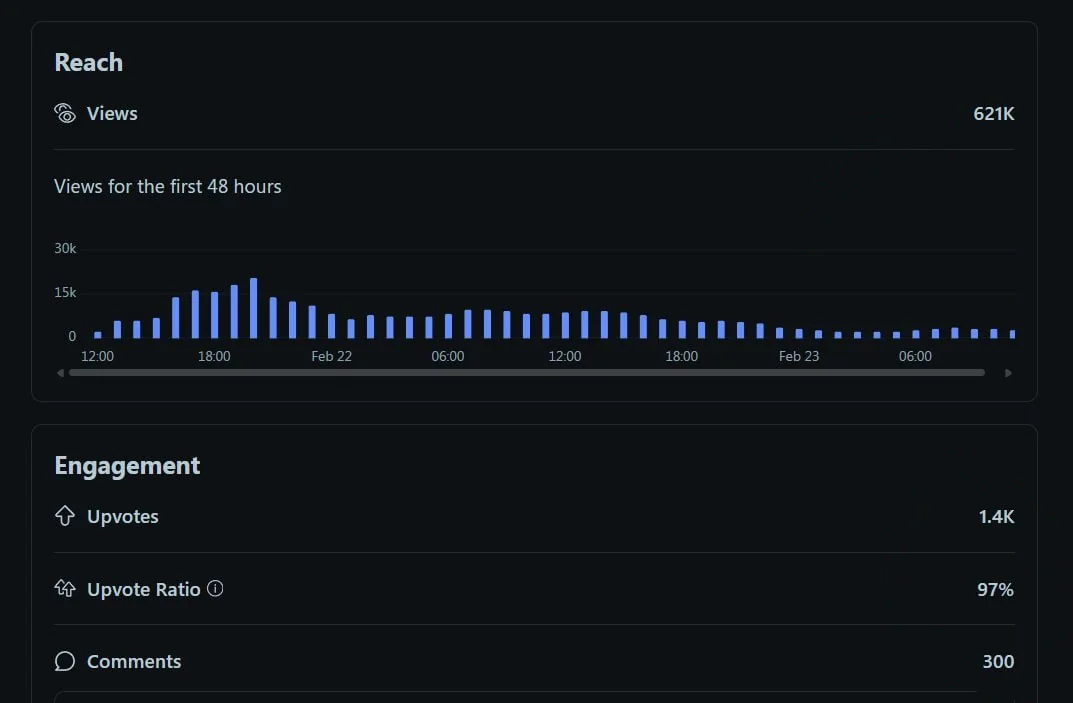
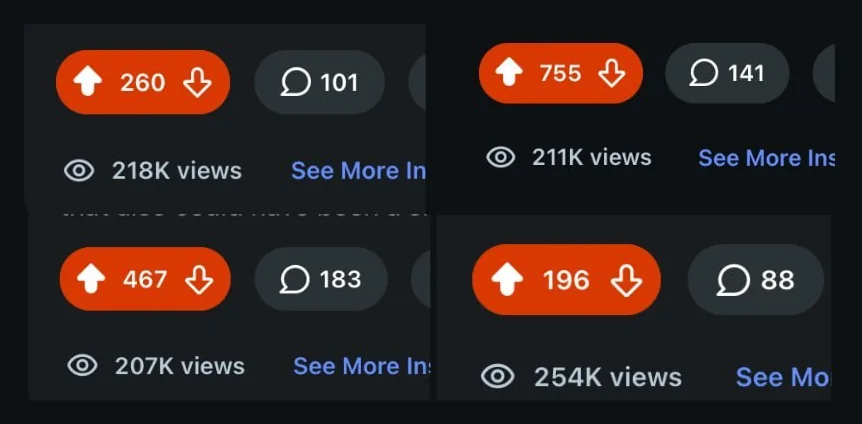
Our posts get seen. 9.5M views across 9 posts.

9.5M views
across 9 of our posts, from Reddit’s own post insights
7.5M621K292K254K218K211K207K166K71K
166K views
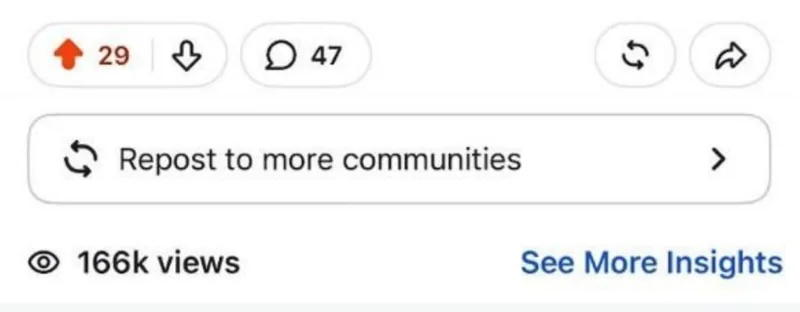
on a post with 29 upvotes. Upvotes undercount how many people read a post.
Views166,000
Upvotes29
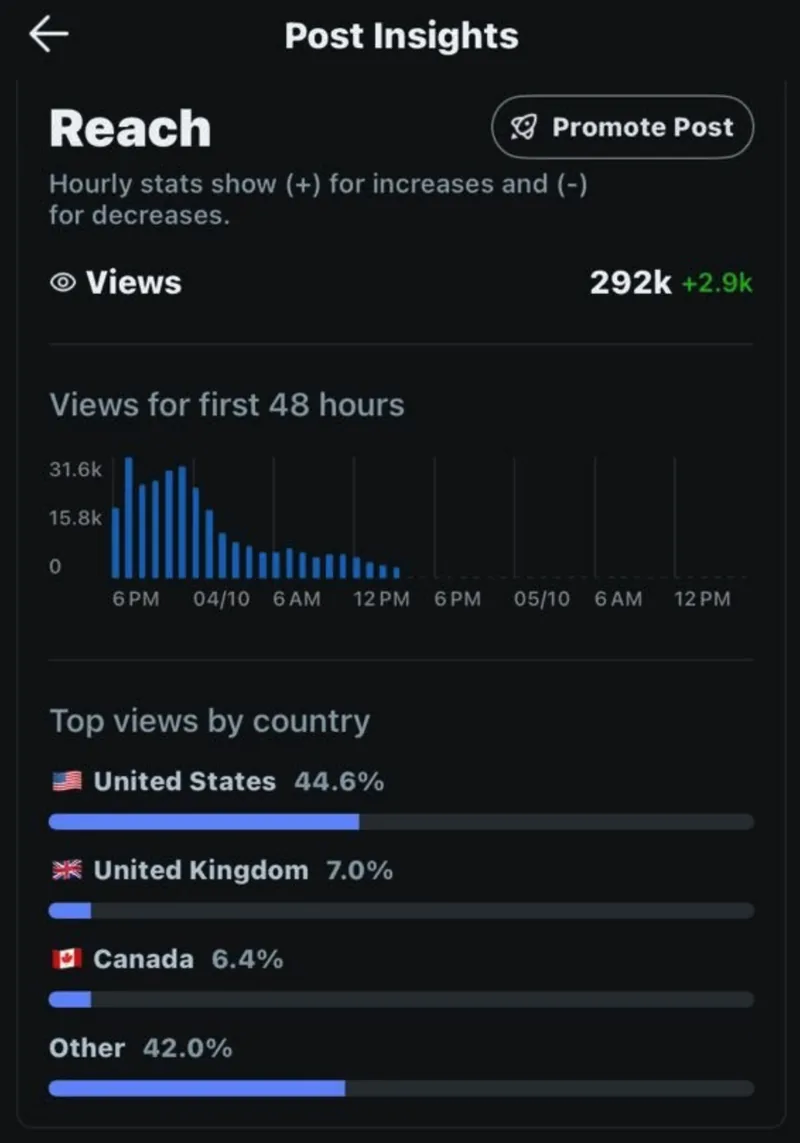
44.6% US
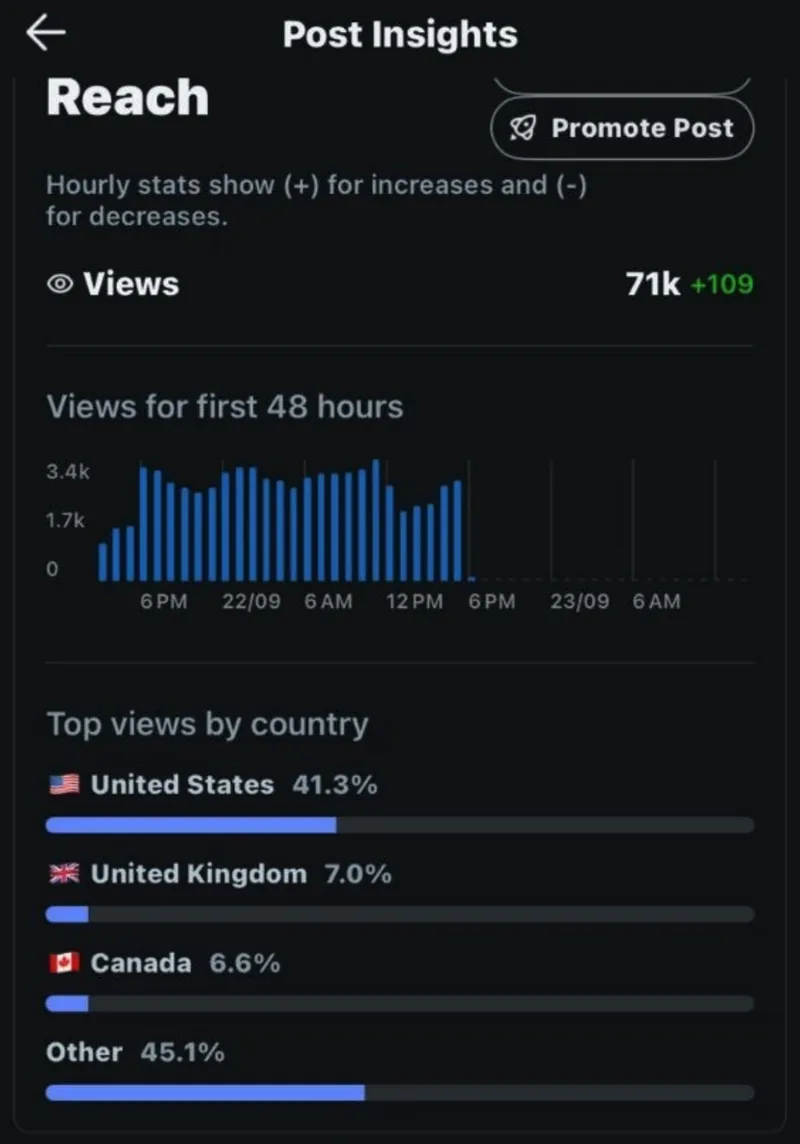
of views on the 292K post came from the US, and 41.3% on the 71K one. The UK and Canada came next, at 6–7% each.
US 44.6%UK 7.0%Canada 6.4%Other 42.0%
Reddit post with 7.5M views, 53.1K upvotes and 2,555 comments
7.5M views · 53.1K upvotes · 2,555 comments
Reddit post insights: 621K views, 1.4K upvotes, 97% upvote ratio, 300 comments
621K views · 1.4K upvotes, 97% upvoted · 300 comments
Four Reddit posts with 254K, 218K, 211K and 207K views
254K, 218K, 211K, 207K views · four posts
Reddit post insights: 292K views, 44.6% from the United States
292K views · 44.6% from the US
Reddit post insights: 71K views, 41.3% from the United States
71K views · 41.3% from the US
Reddit post with 166K views, 29 upvotes and 47 comments
166K views · 29 upvotes · 47 comments
10 · Plans

Pick the goal, then the number of accounts. Before the beta, we’d start on Exposure with 3.

Exposurestart here

Warm-up, seeding and launch

Accounts with history before January, the problem in front of the right readers, then the beta.

$3,500per account
a month
Accounts
2 minimum, more as needed
Posts
20 per account a month. Before the beta, warm-up answers count toward the 20.
Where
The live threads on limits, token bills, local models and idle Macs and GPUs, the open argument threads, then one launch post per subreddit in beta week.
Measured at day 90Threads naming Heavy Metal 0/81Waitlist and beta signups from Reddit
Ranking

Google and AI answers SEO & AEO

Heavy Metal inside the threads Google ranks, once there’s a beta to point to.

$3,500per account
a month
Accounts
2 minimum, more as needed
Posts
About 10 per account a month, each one targeted
Where
Replies in the 49 open threads that rank, plus new posts written to rank where the Reddit result is thin. New posts name Heavy Metal without linking to it.
Measured at day 90Ranking threads naming Heavy Metal 0/49Reddit posts about Heavy Metal Network 0
Mix

Half and half

Half the posts for reach, half for ranking. A fit once the beta is out.

$3,500per account
a month
Accounts
2 minimum, more as needed
Posts
20 per account a month, 10 for each goal
Where
Both lists, split evenly on every account.
Measured at day 90Threads naming Heavy Metal 0/81Ranking threads 0/49Signups from Reddit
post for reach: warm-up, seeding, launchtargeted post for rankingno post
20 / account / month
post that stays upremoved by moderators, then replaced

Some posts get removed. Out of 20, around 3 can be. Each removed post is replaced with a new one, so every account still delivers its full count for the month.

Price by number of accounts

AccountsPer monthExposure & MixRanking
2 accountsMinimum$7,0002 × $3,50040posts a month20posts a month
3 accountsWe recommend starting here$10,5003 × $3,50060posts a month30posts a month
+Each added accountWhen you need more reach+$3,500per account+20posts a month+10posts a month